1 Million Tokens Are Not
An Agent's Memory

Ashish Tiwari  |  Search AI Specialist @ Elastic

The argument

Three claims, and every one of them is measured

Part one

The window is not memory

Advertised length is not usable length.

Part two

Vectors are not retrieval

Embedding recall has a hard ceiling.

Part three

How we solve it

Inside Agent Builder, with the constants.

Evidence 1

The window is not what the spec sheet says

250x

gap between the largest advertised window and its measured effective length.

ModelClaimedEffective
LWM (7B)1M<4K
GPT-4128K64K
Yi (34B)200K32K
accuracy closed book, no documents: 56.1% 75.8% 53.8% 63.2% firstmiddlelast

Accuracy by answer position, 20 document QA.

Sources: RULER, COLM 2024  |  Lost in the Middle, TACL 2024
Evidence 2

It breaks at 32K, not at 1M
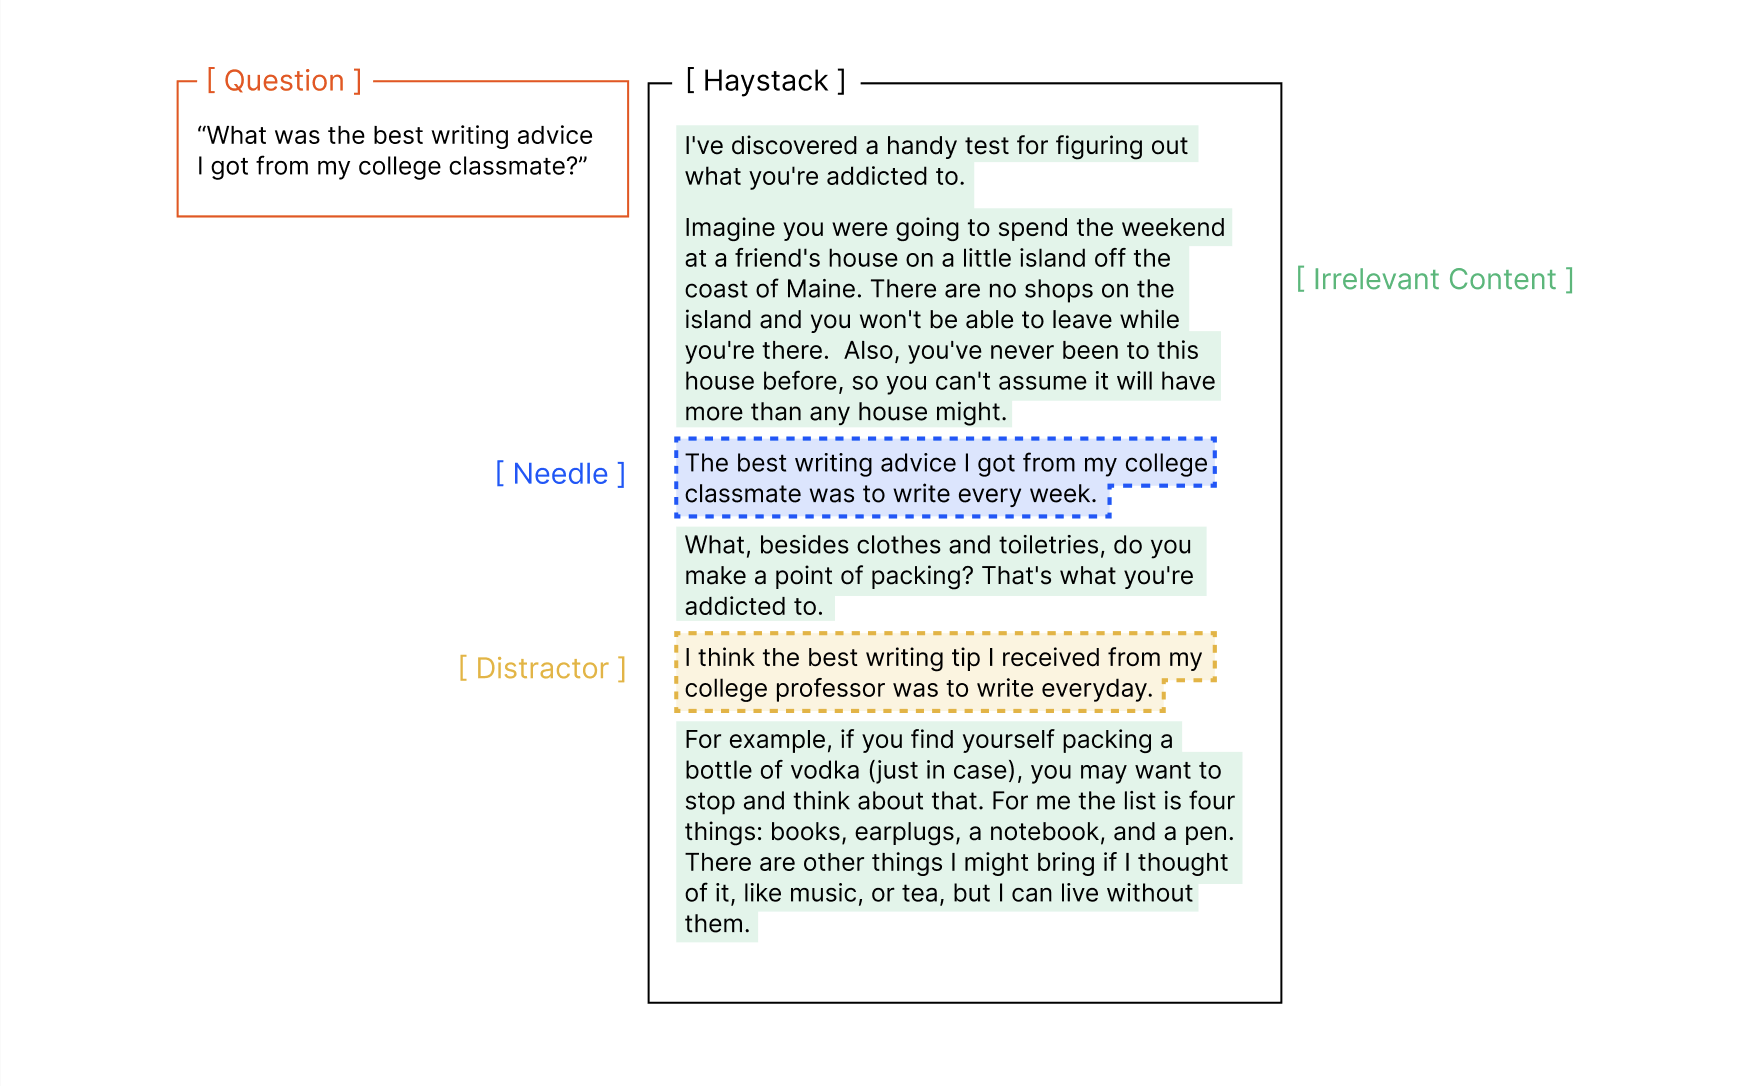
NoLiMa: needle and distractor share no words with the question. No keyword overlap to latch onto.
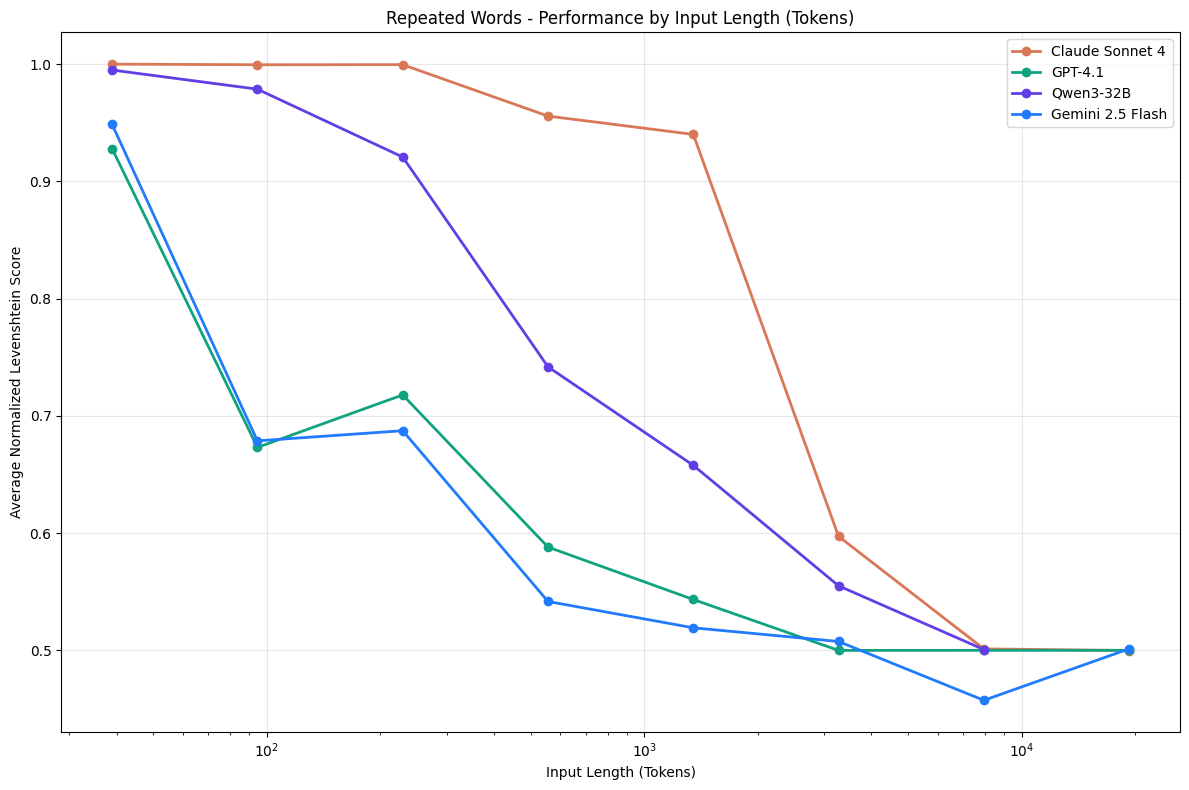
18 models. 194,480 calls. Same result.

Sources: NoLiMa, ICML 2025  |  Chroma, Context Rot
Evidence 3. Benchmark, then production

Wrong context is worse than no context

Controlled benchmark — long-term chat memory
SystemEvidence onlyFull historyDrop
GPT-4o0.8700.606-30%
Llama 3.1 70B0.7440.334-55%

Same model and same question, so the only thing that changed is who picked the context.

Production telemetry — one year, 209,220 threads
Found the answer

80,887 threads

9.81
Found nothing

65,624 threads

9.18
Found part of it

9,732 threads

8.15

An empty result fails loudly. Half an answer just sounds right but could be risky.
Sources: LongMemEval, ICLR 2025  |  AI Year in Review, production telemetry 2025

A context window is a cache.
Memory decides what goes in it

The obvious fix, and its blind spot

Three questions that break vector search

Anthropic: "could miss the exact TS-999 match"
The ceiling

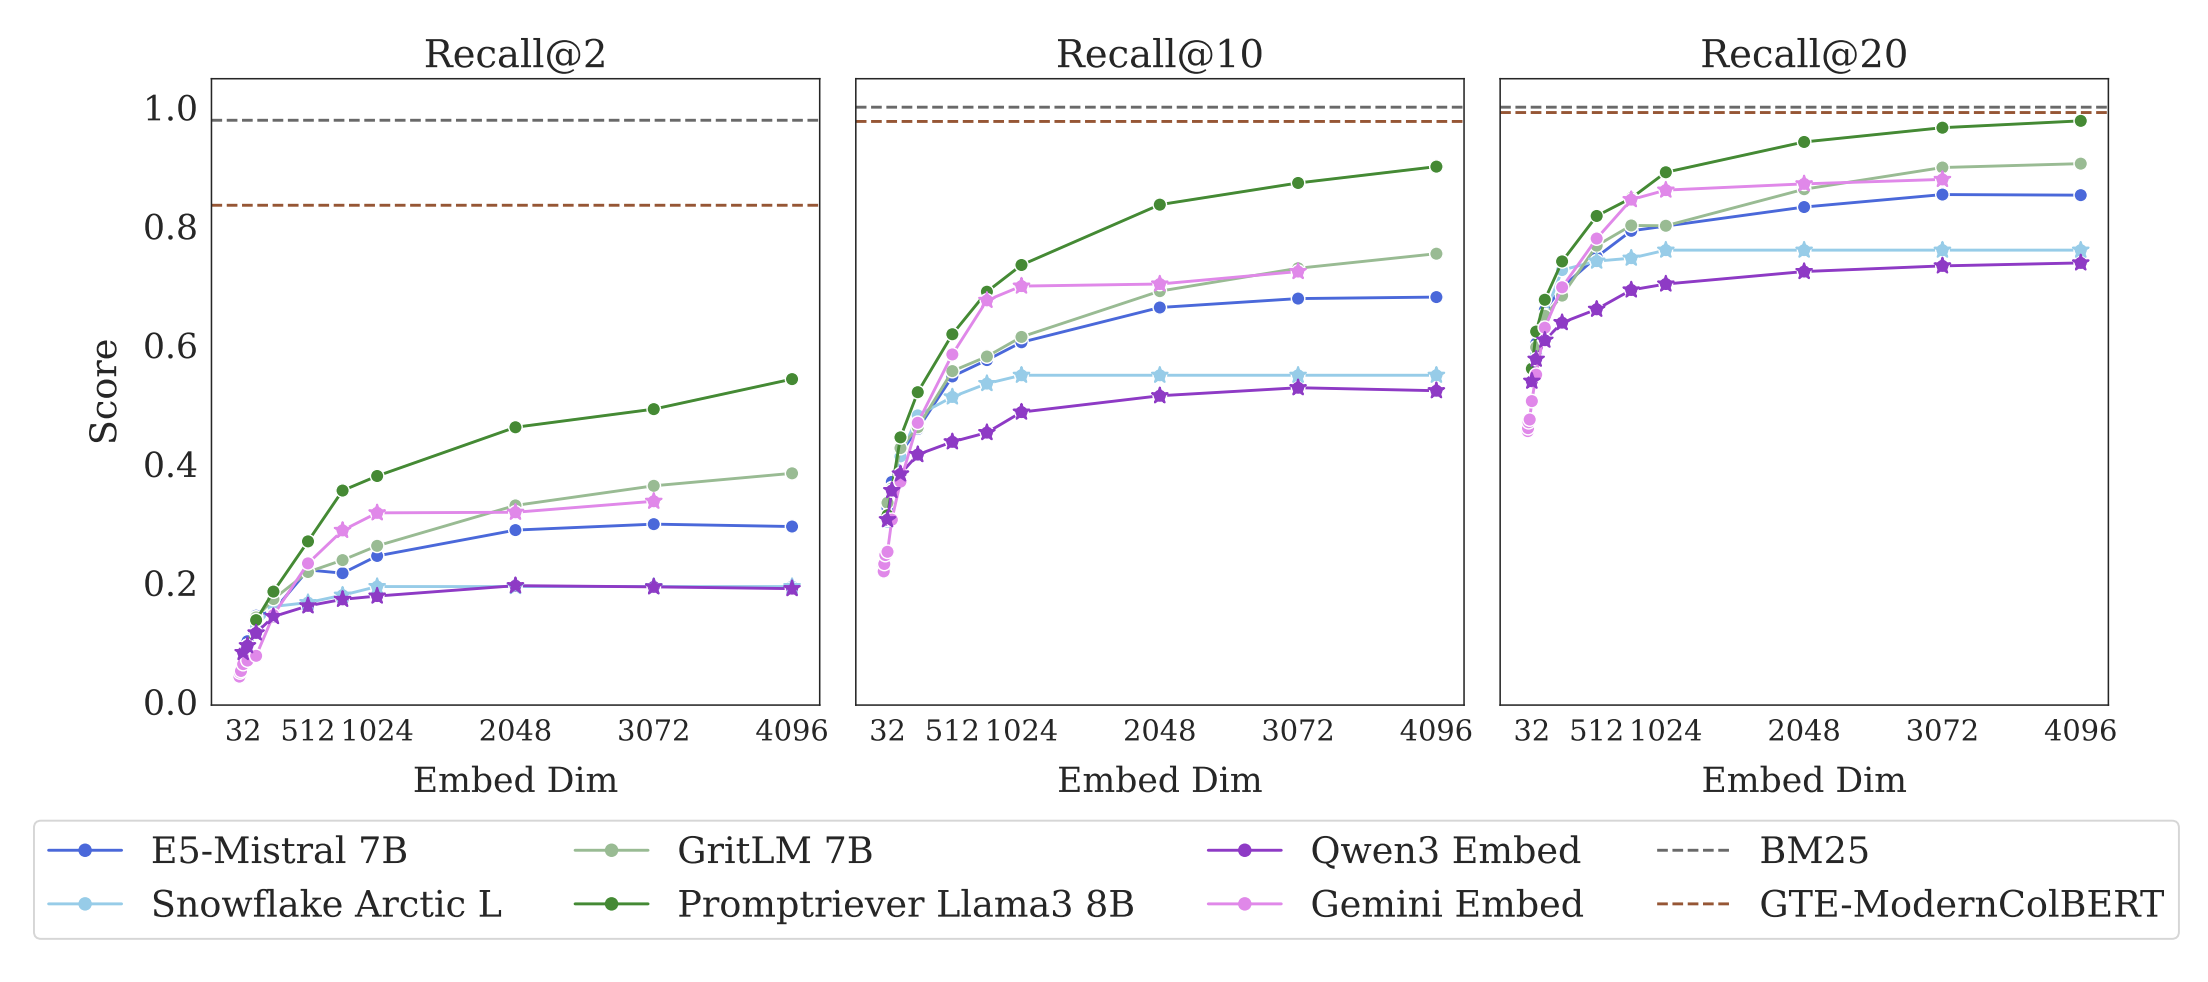
Embeddings have a proven upper bound

One vector of size d can only ever express so many different answers.

9 of 18

BEIR datasets where plain keyword search beat every dense retriever tested.
Sources: DeepMind, Limitations of Embedding-Based Retrieval  |  BEIR, NeurIPS 2021
What fixes it

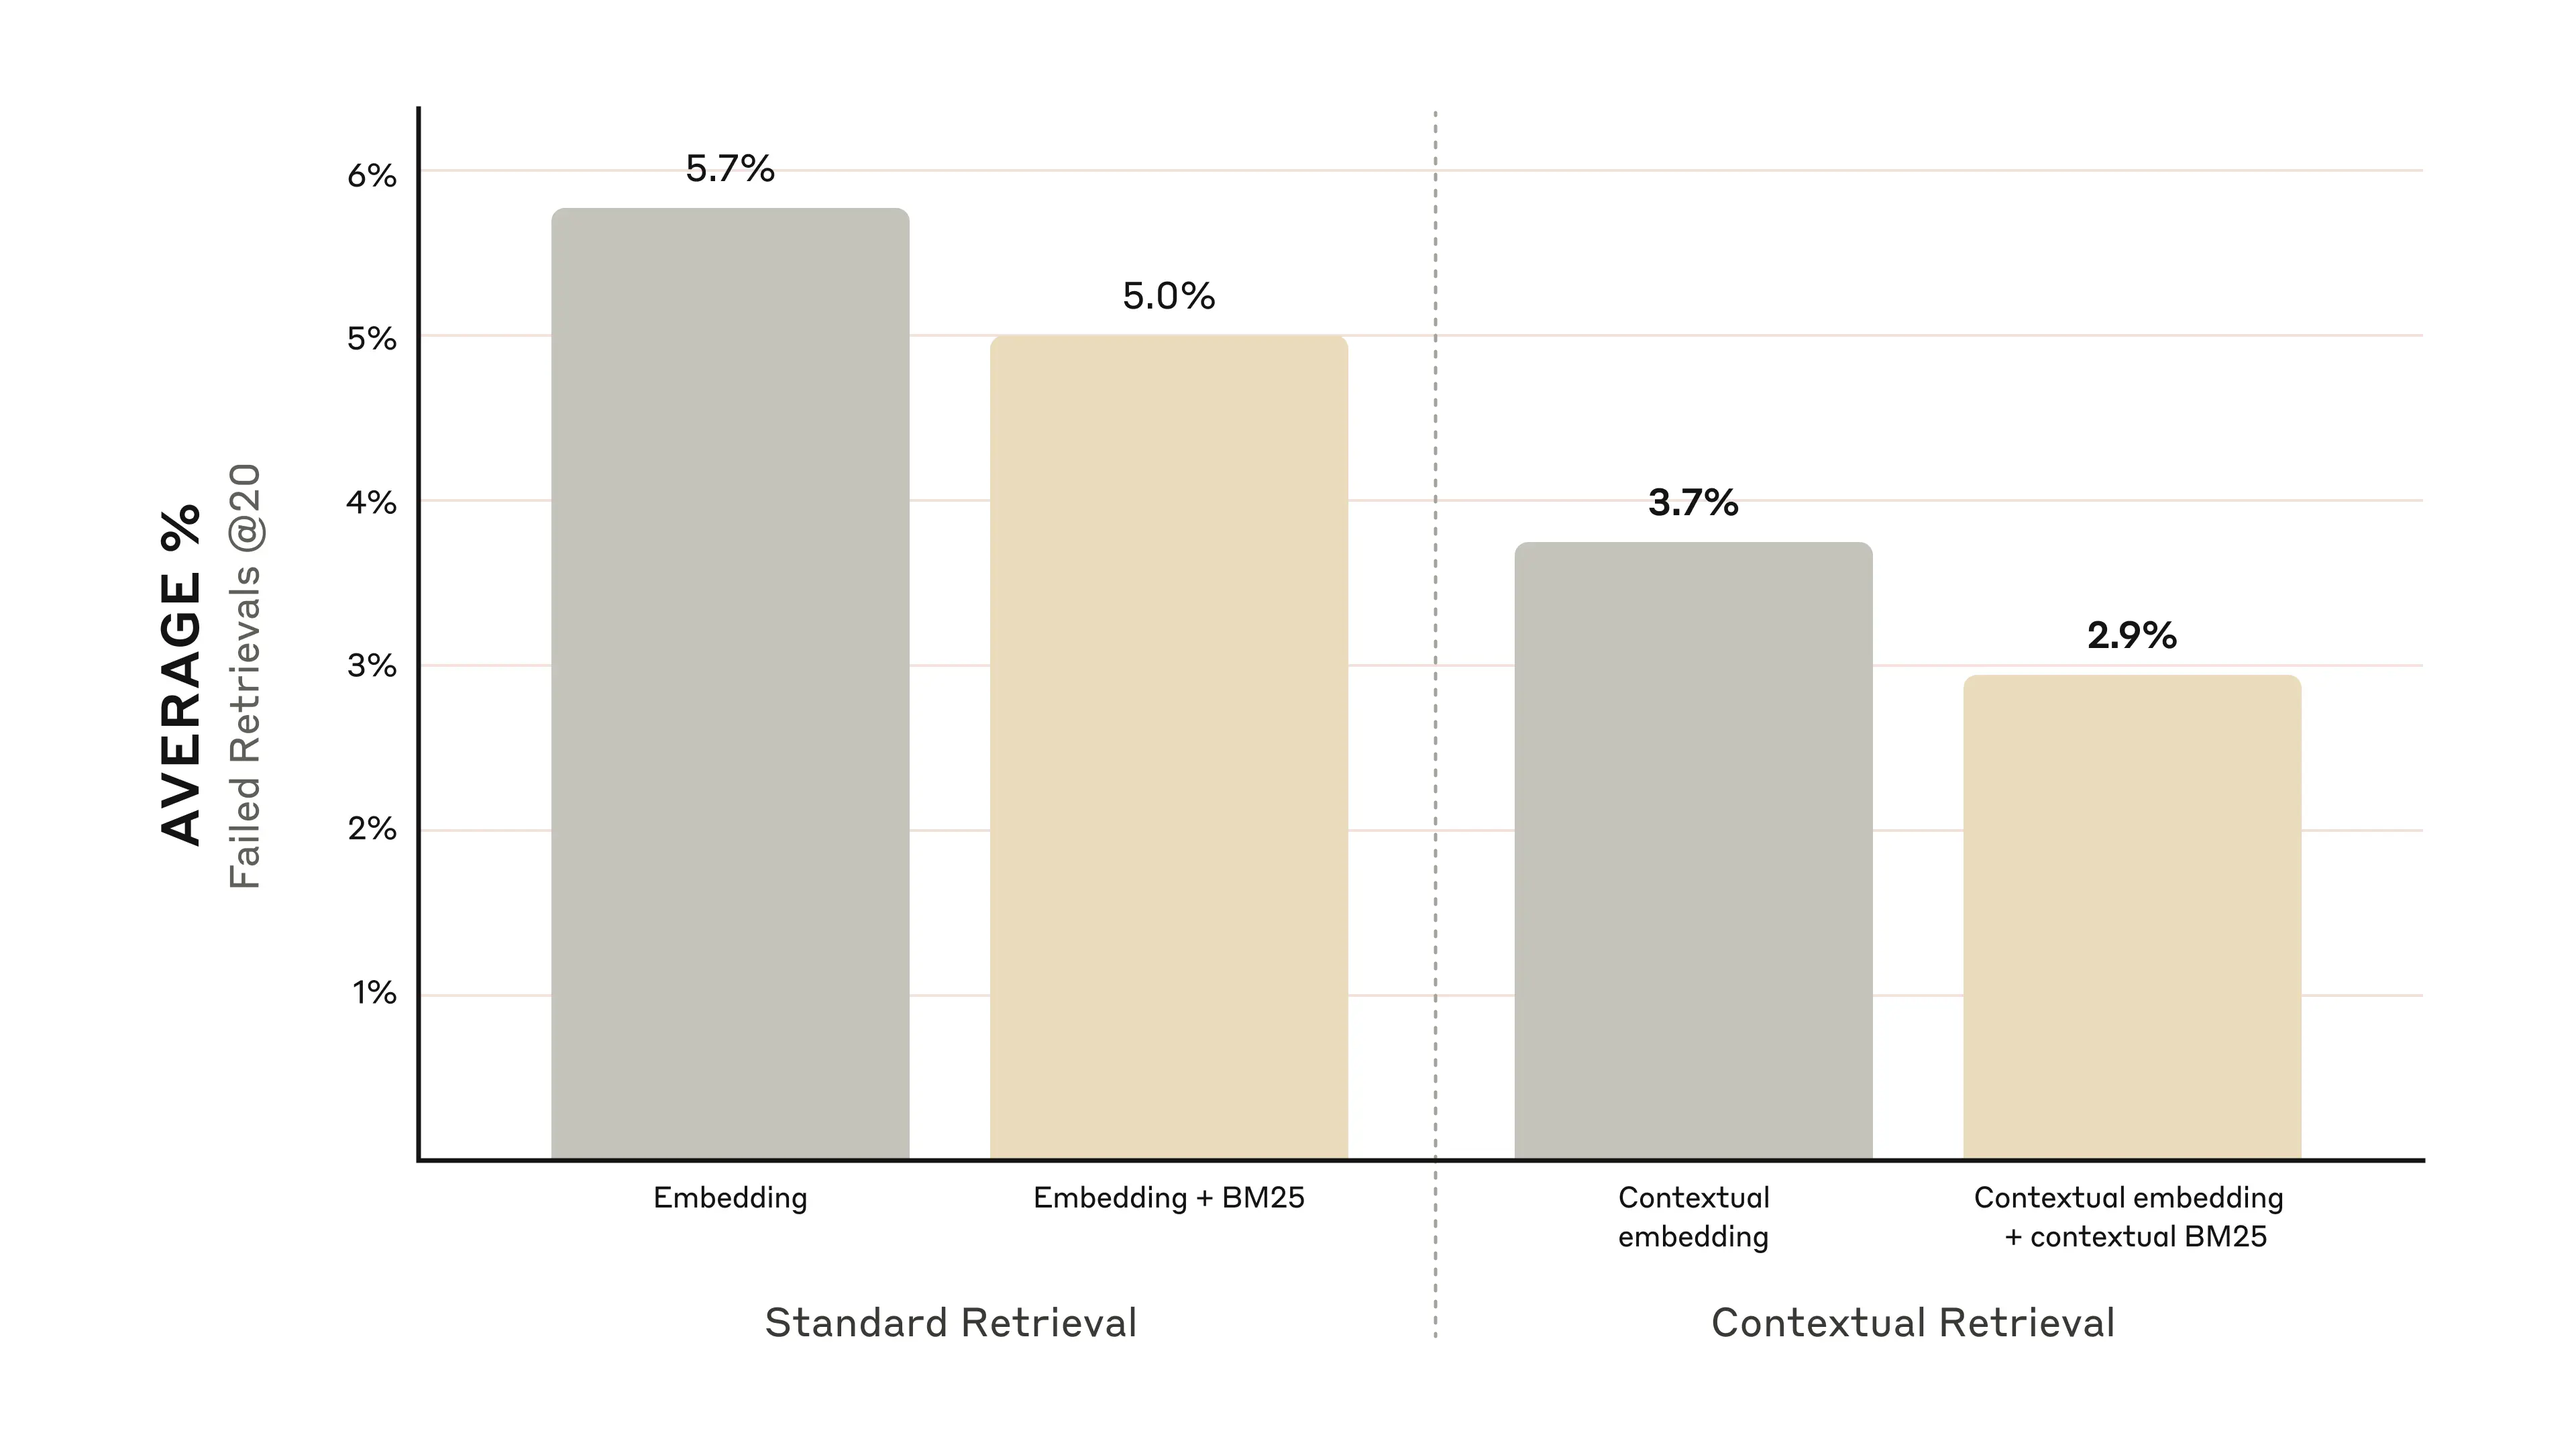
Every signal covers another one's blind spot

Adding keyword search to embeddings cut failed retrievals by nearly half.

Add a reranking pass on top and it drops again, to 1.9%.
Keyword: IDs and codes
Semantic: meaning
Filters: time and tenant
Rerank: the final order
Source: Anthropic, Contextual Retrieval
What that means for memory

There is no single memory. There are four

Working

This turn

Episodic

What happened

Semantic

What is true

Procedural

What works

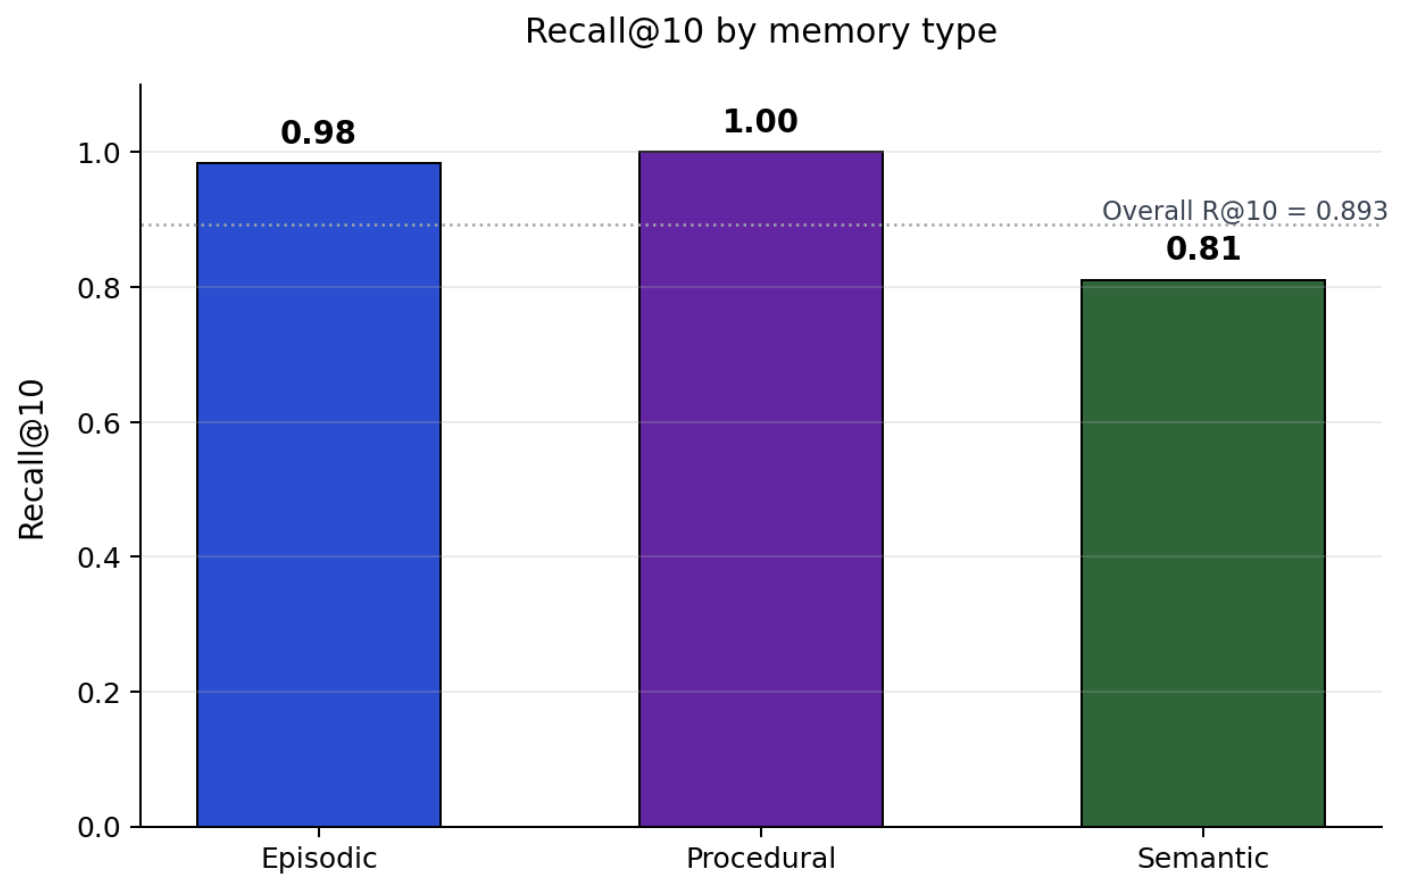
Same pipeline, same corpus, and the stores land twenty points apart.

Elastic reference build

80 keyword + 80 vector
 → rank fusion
 → cross encoder rerank
time decay + usage boost
per user access control
Source: Agent memory with hybrid retrieval, Search Labs

So we stopped enlarging the window
and started engineering the retrieval

Inside Agent Builder

Load the context you need, when you need it

Drop in: images/skills_as_stubs.png
"Skills as stubs" diagram, 1328x1176, from the section
"Getting agents to know what you know"

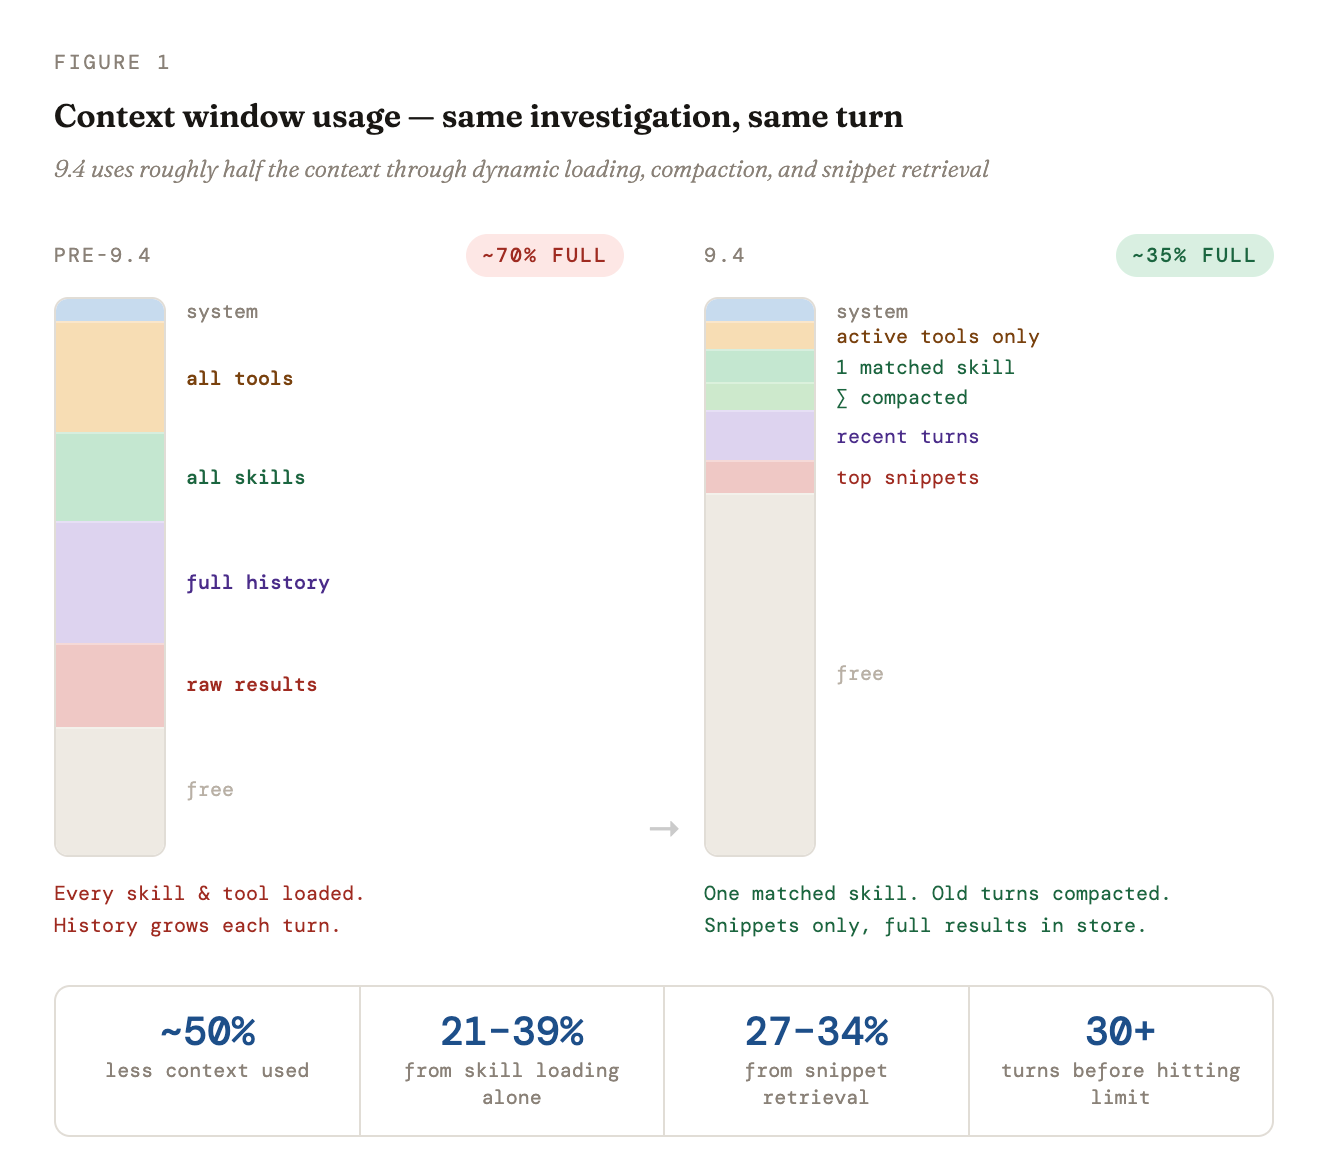
Skills load only when the agent needs them. Everything else stays a lightweight stub.

Skills as stubs
21-39%

fewer input tokens

Top snippets, not documents
27-34%

fewer input tokens

Source: Elastic Agent Builder: context management
Inside Agent Builder

Agents start contradicting themselves at turn twelve

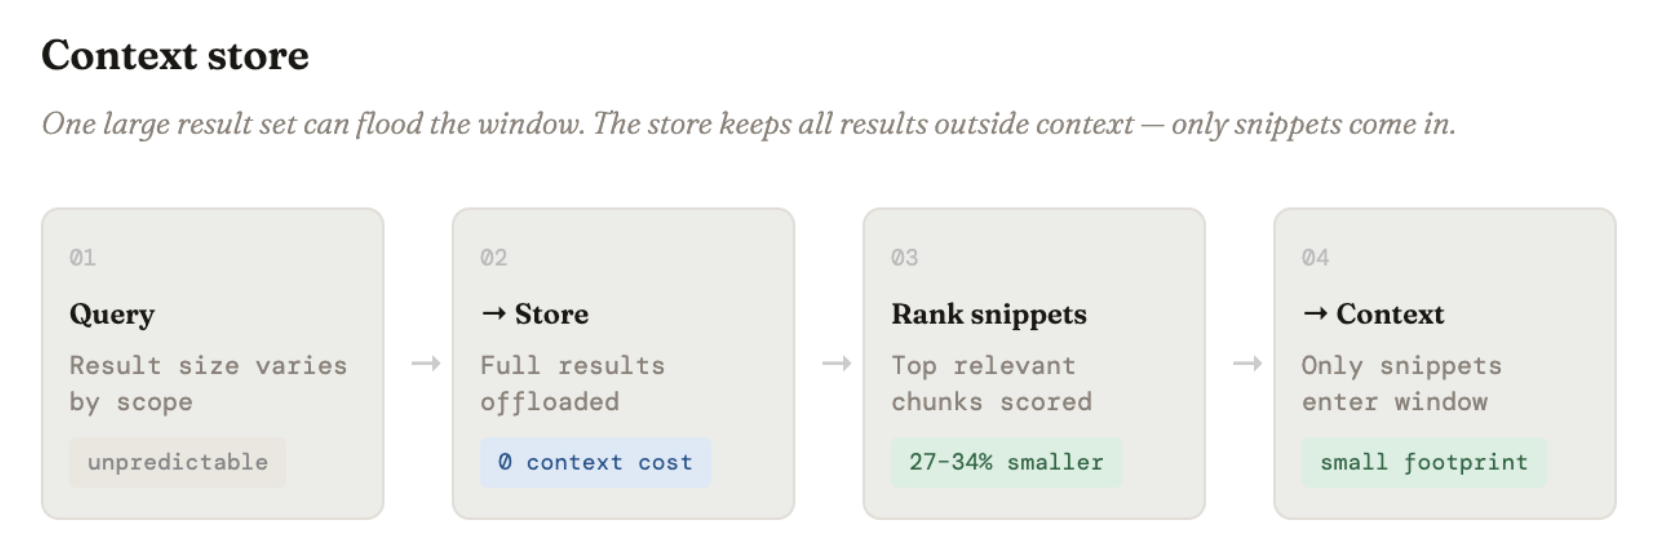
Drop in: images/context_store.png
the context store diagram from the same post

"Eventually the context window fills up, fidelity drops and token costs climb."

Selective compaction

Keep what matters for the next turn, rather than dropping the oldest.

The context store

Results sit in an in-memory file store and enter context only when needed.

Chats past 30 turns, at up to 40% lower token cost.

Source: Elastic Agent Builder: context management
Take these with you

Five things to steal, whatever you are building on

01   Load instructions lazily. Stubs first, full text only when needed.
02   Keep large results out of the conversation. Park them, pull on demand.
03   Return the passages that matter, not whole documents.
04   Compact for what the next turn needs. Oldest is not the same as least useful.
05   Connect at the source, with the user's permissions. Do not let agents hoard copies.
Source: Elastic Agent Builder: context management
Build this Monday

Two paths, and five numbers worth watching

When you write
Split on structure, not on size
Pull out entities and decisions
Index keyword and vector, both
Tag time, actor, tenant
When you read
Route the question to the right store
Search both ways, under filters
Fuse, then rerank
Budget the tokens, log what you sent

Five to watch: recall@10, MRR, tokens per turn, compaction events, and partial hits.

Tokens are just fuel,
retrieval is the engine,
and memory is the architecture in between

Ashish Tiwari  |  Search AI Specialist @ Elastic
LinkedIn QR code

Connect on LinkedIn

References

Every number here, with its source

The problem
RULER, COLM 2024
Lost in the Middle, TACL 2024
NoLiMa, ICML 2025
Context Rot, Chroma 2025
LongMemEval, ICLR 2025
Manus, Context Engineering for AI Agents

The retrieval ceiling
DeepMind, Limitations of Embedding-Based Retrieval
BEIR, NeurIPS 2021
Anthropic, Contextual Retrieval

How we solve it
Agent memory: hybrid retrieval and access control
Elastic Agent Builder: context management
Search tools for context engineering
Relevance and context engineering for agents
Hybrid retrieval and rank fusion benchmarks
AI Year in Review, production telemetry 2025

← → navigate   N notes   F fullscreen